
Running Qwen 3.8 Flash Next on Strata: Architecture and Local Limits
A technical evaluation of the Strata inference engine for Qwen 3.8 Flash Next, examining tiered MoE offloading, sub-3-bit quantization loss, and deployment limits.

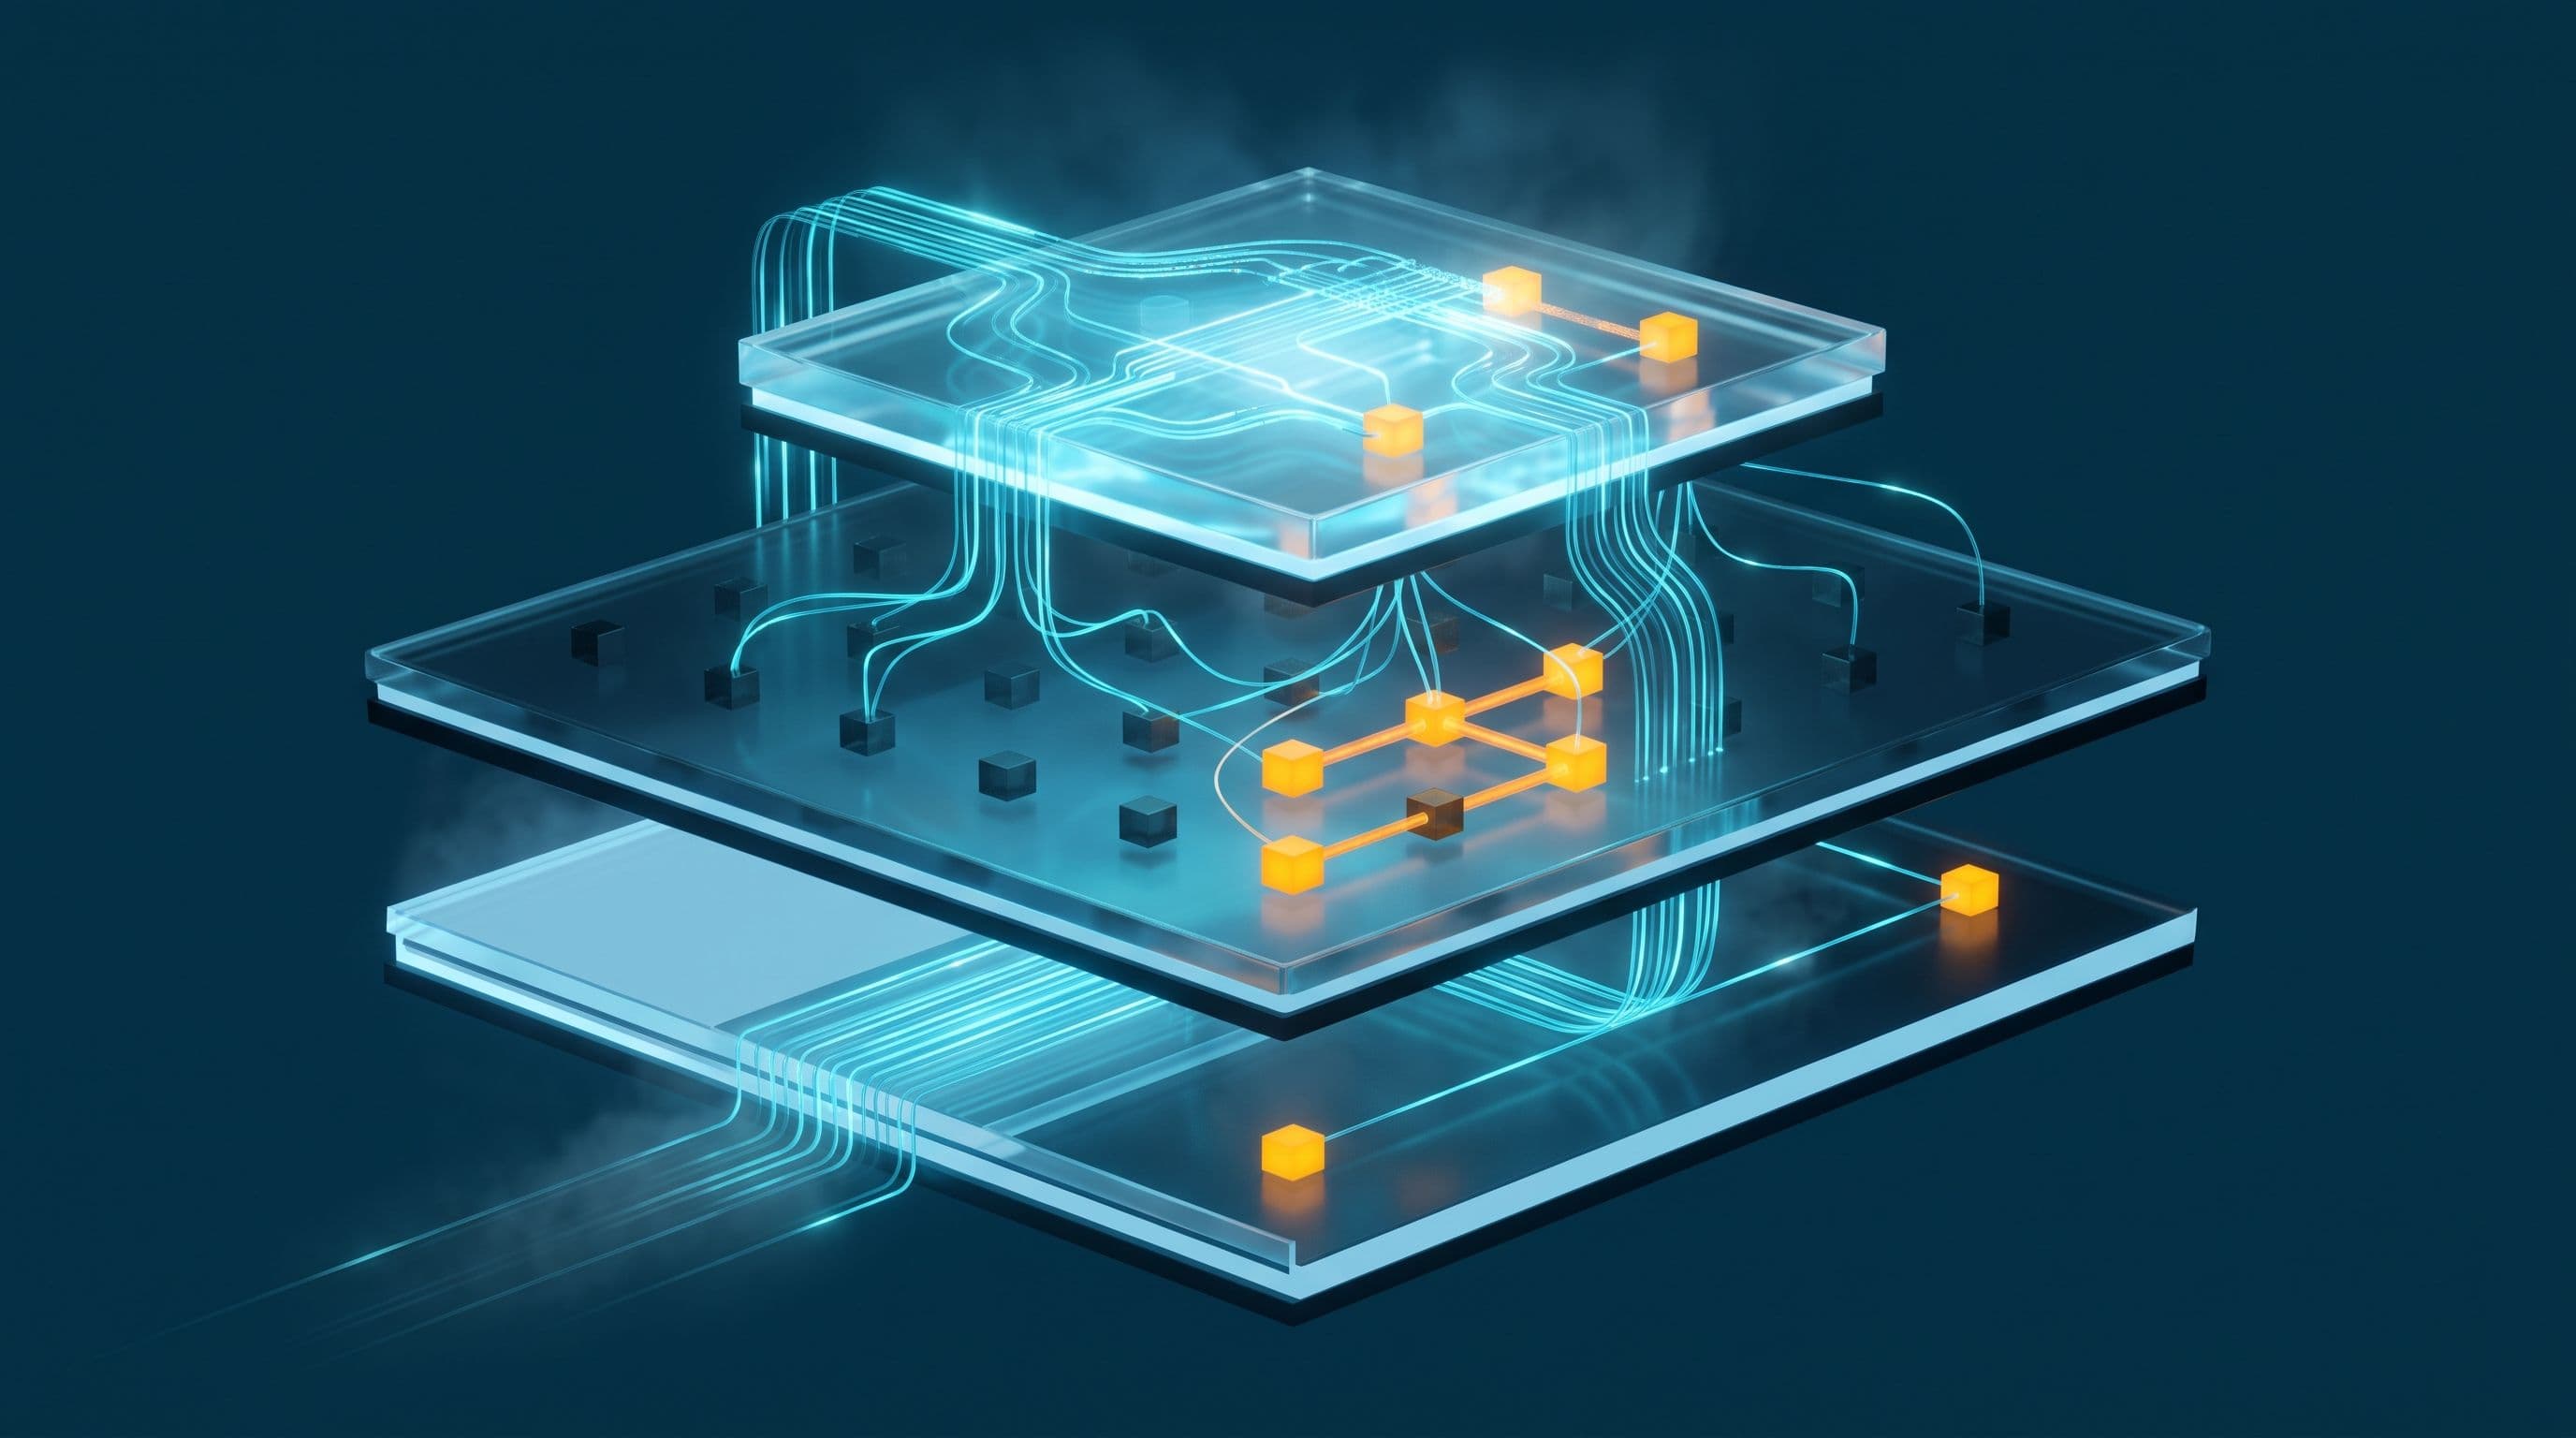
The open-source Strata engine has attracted substantial developer interest by claiming to execute the massive Qwen 3.8 Flash Next model on consumer gaming desktops equipped with a single 12 GB VRAM graphics card. For software engineers evaluating local deployment alternatives, discerning the underlying systems architecture from community performance claims is vital before committing development time or upgrading hardware.
Computational Footprint and MoE Routing Realities
While the official Strata repository on GitHub advertises running a 125-billion-parameter architecture, underlying technical specifications reveal a 180-billion total parameter footprint. The primary computing neural network accounts for 125 billion parameters, augmented by a 51-billion-parameter n-gram embedding lookup table and a 4-billion-parameter multi-token prediction structure. The full installation download requires approximately 70 GB and 80 GB of free storage.
As documented in the Qwen 3.8 Flash Next model card on Hugging Face, the architecture relies on an ultra-fine-grained Mixture-of-Experts (MoE) design containing 24,576 total experts, activating only 10 experts per generated token. Attention mechanisms combine Qwen Sparse Attention (QSA) operating at the micro-block level with Gated DeltaNet and gated residual streams, dramatically reducing computational complexity and long-context latency.
Tiered Memory Offloading and Speculative Execution
Strata bridges the physical capacity gap between a 12 GB GPU and a 70 GB model weight payload through coordinated subsystem tiering:
- GPU VRAM: Acts as an execution cache for the most frequently routed experts.
- System RAM: Retains all experts in active host memory, requiring 32 GB minimum and 64 GB for universal profile support.
- NVMe Disk Bus: Pages large static n-gram lookup tables without monopolizing fast memory channels.
- Speculative Decoding: Operates a lightweight draft model to propose candidate token sequences verified concurrently by the base network, yielding a claimed 1.6x to 1.8x acceleration factor.
Quantization Degradation and Operational Boundaries
Achieving generation rates of 62 to 94 tokens per second on an RTX 5070 card requires aggressive sub-3-bit quantization, such as IQ3_XXS and Q2_0. While community benchmarks cited on Hacker News discussion threads report an 89.1% solve rate on specific programming evaluations, community testing also revealed significant spatial degradation. In an empirical 50-image coordinate benchmark, Strata recorded a median error distance of 154.8 pixels compared to 46.5 pixels on llama.cpp using identical model weights.
Scroll horizontally to see all columns
| Architectural Attribute | Strata MoE (125B Active / IQ3_XXS) | Dense Local Alternative (e.g., 27B / Q4_K_M) |
|---|---|---|
| GPU VRAM Threshold | 12 GB minimum (RTX 20–50 or modern AMD) | 16–24 GB for complete onboard residency |
| Host RAM Consumption | 32–64 GB (up to 96% system saturation) | 16–32 GB with stable operating headroom |
| Prompt Ingestion Latency | ~1 minute per 30,000 input tokens | Low-latency unified VRAM processing |
| Generation Throughput | 62–94 tokens/s (author benchmark) | 20–50 tokens/s depending on runtime setup |
| Multimodal Precision | Elevated coordinate error risk under extreme quants | Consistent baseline fidelity across benchmarks |
Furthermore, architectural notes published on VRAMCalculator technical analysis confirm that host RAM saturation reaches up to 96%, starving concurrent workloads. Prompt ingestion latency remains high, taking approximately one minute per 30,000 tokens, while default server parameters enforce single-request concurrency.
Engineering Verification Protocol
Critically, available source documentation provides zero empirical verification regarding Arabic language tokenization efficiency or semantic comprehension under sub-3-bit compression. Teams considering deployment should follow a strict verification protocol:
- Benchmark Coding Fidelity: Validate local integration against complex private repositories via the provided
POST /v1/responsesAPI endpoint before relying on coding automation. - Audit Non-Latin Syntax: Quantify semantic drift in Arabic and multilingual text against unquantized cloud baselines.
- Isolate Hardware Workloads: Ensure host machines are not running memory-sensitive production databases alongside Strata's saturated memory allocator.
Related Articles
View all articles →
Getting Started with DeerFlow: Setup Wizard, Docker, and Practical Workflows
A practical guide to configuring DeerFlow, setting up model providers, running exact Docker commands, verifying startup, and executing document comparisons.
8 AI Coding Agent Tools for Verification, Efficiency, and UI
A technical guide to eight developer tools for coding agents, covering runtime verification, token reduction, 3D generation, UI skills, and linter rules.
Coordinating AI Agents with Paperclip: A Practical Local Setup Guide
Get started with Paperclip locally using Node 24.11+ and npx. Configure a single agent for a bounded task, track spend budgets on localhost:3100, and resolve common registry hurdles.
Want this for your product?
Send a short note about your project. We will review it and explain the next useful step.
Contact Our Team